Halloween Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Professional-Data-Engineer Exam Questions and Answers by mae

Page: 5 / 14

Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview :

Exam Name: Databricks Certified Data Engineer Professional Exam
Exam Code: Databricks-Certified-Professional-Data-Engineer Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 202 Q&A's Shared By: mae
Question 20

A nightly job ingests data into a Delta Lake table using the following code:
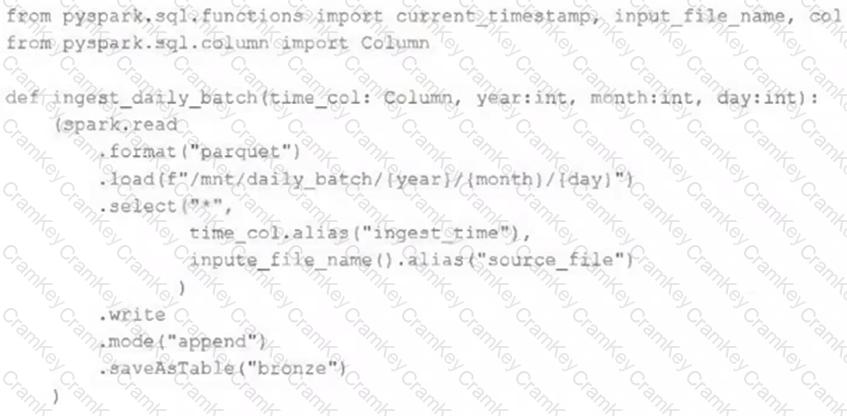
Questions 20

The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.

Which code snippet completes this function definition?

def new_records():

Options:

A.

return spark.readStream.table( " bronze " )

B.

return spark.readStream.load( " bronze " )

C.

Option C 20

D.

return spark.read.option( " readChangeFeed " , " true " ).table ( " bronze " )

E.

Option E 20

Discussion
Question 21

A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high-cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time.

Which command should the data engineer implement?

Options:

A.

Alter the table to use Hive-Style Partitions + Z-ORDER and implement a periodic OPTIMIZE command.

B.

Alter the table to use Liquid Clustering and implement a periodic OPTIMIZE command.

C.

Alter the table to use Hive-Style Partitions and implement a periodic OPTIMIZE command.

D.

Alter the table to use Z-ORDER and implement a periodic OPTIMIZE command.

Discussion
Ari
Can anyone explain what are these exam dumps and how are they?
Ocean Sep 23, 2026
They're exam preparation materials that are designed to help you prepare for various certification exams. They provide you with up-to-date and accurate information to help you pass your exams.
Sam
Can I get help from these dumps and their support team for preparing my exam?
Audrey Sep 25, 2026
Definitely, you won't regret it. They've helped so many people pass their exams and I'm sure they'll help you too. Good luck with your studies!
Addison
Want to tell everybody through this platform that I passed my exam with excellent score. All credit goes to Cramkey Exam Dumps.
Libby Sep 19, 2026
That's good to know. I might check it out for my next IT certification exam. Thanks for the info.
Cody
I used Cramkey Dumps to prepare and a lot of the questions on the exam were exactly what I found in their study materials.
Eric Sep 2, 2026
Really? That's great to hear! I used Cramkey Dumps too and I had the same experience. The questions were almost identical.
Syeda
I passed, Thank you Cramkey for your precious Dumps.
Stella Sep 19, 2026
That's great. I think I'll give Cramkey Dumps a try.
Question 22

To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.

Which SQL query should the team run from the System catalog to achieve this?

Options:

A.

SELECT sku_name,

identity_metadata.created_by AS user_email,

COUNT(usage_quantity) AS total_dbus

FROM system.billing.usage

GROUP BY user_email, sku_name

ORDER BY total_dbus DESC

LIMIT 10

B.

SELECT identity_metadata.run_as AS user_email,

SUM(usage_quantity) AS total_dbus

FROM system.billing.usage

GROUP BY user_email

ORDER BY total_dbus DESC

LIMIT 10

C.

SELECT sku_name,

identity_metadata.created_by AS user_email,

SUM(usage_quantity * usage_unit) AS total_dbus

FROM system.billing.usage

GROUP BY user_email, sku_name

ORDER BY total_dbus DESC

LIMIT 10

D.

SELECT sku_name,

usage_metadata.run_name AS user_email,

SUM(usage_quantity) AS total_dbus

FROM system.billing.usage

GROUP BY user_email, sku_name

ORDER BY total_dbus DESC

LIMIT 10

Discussion
Question 23

A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities.

Which type of Databricks cluster should the data engineer configure?

Options:

A.

A lightweight single-node cluster with low worker node count to reduce costs.

B.

A high-concurrency cluster designed for interactive SQL workloads.

C.

An all-purpose cluster always kept running to ensure low-latency job startup times.

D.

A job cluster configured to autoscale across multiple workers during the pipeline run.

Discussion
Page: 5 / 14
Title
Questions
Posted

Databricks-Certified-Professional-Data-Engineer
PDF

$31.5  $104.99

Databricks-Certified-Professional-Data-Engineer Testing Engine

$37.5  $124.99

Databricks-Certified-Professional-Data-Engineer PDF + Testing Engine

$49.5  $164.99
