Black Friday VIP Weekend - 75% Discount offer - Ends in 0d 00h 00m 00s - Coupon code: 75brite

Databricks Updated Databricks-Machine-Learning-Associate Exam Questions and Answers by laiba

Page: 4 / 5

Databricks Databricks-Machine-Learning-Associate Exam Overview :

Exam Name: Databricks Certified Machine Learning Associate Exam
Exam Code: Databricks-Machine-Learning-Associate Dumps
Vendor: Databricks Certification: ML Data Scientist
Questions: 74 Q&A's Shared By: laiba
Question 16

Which of the following tools can be used to distribute large-scale feature engineering without the use of a UDF or pandas Function API for machine learning pipelines?

Options:

A.

Keras

B.

Scikit-learn

C.

PyTorch

D.

Spark ML

Discussion
Question 17

A machine learning engineer wants to parallelize the training of group-specific models using the Pandas Function API. They have developed thetrain_modelfunction, and they want to apply it to each group of DataFramedf.

They have written the following incomplete code block:
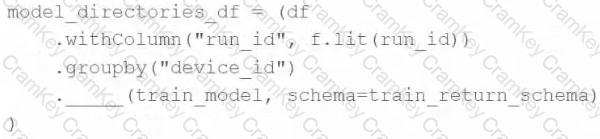
Questions 17

Which of the following pieces of code can be used to fill in the above blank to complete the task?

Options:

A.

applyInPandas

B.

mapInPandas

C.

predict

D.

train_model

E.

groupedApplyIn

Discussion
Question 18

A machine learning engineer is trying to scale a machine learning pipeline by distributing its single-node model tuning process. After broadcasting the entire training data onto each core, each core in the cluster can train one model at a time. Because the tuning process is still running slowly, the engineer wants to increase the level of parallelism from 4 cores to 8 cores to speed up the tuning process. Unfortunately, the total memory in the cluster cannot be increased.

In which of the following scenarios will increasing the level of parallelism from 4 to 8 speed up the tuning process?

Options:

A.

When the tuning process in randomized

B.

When the entire data can fit on each core

C.

When the model is unable to be parallelized

D.

When the data is particularly long in shape

E.

When the data is particularly wide in shape

Discussion
Question 19

A data scientist is wanting to explore the Spark DataFrame spark_df. The data scientist wants visual histograms displaying the distribution of numeric features to be included in the exploration.

Which of the following lines of code can the data scientist run to accomplish the task?

Options:

A.

spark_df.describe()

B.

dbutils.data(spark_df).summarize()

C.

This task cannot be accomplished in a single line of code.

D.

spark_df.summary()

E.

dbutils.data.summarize (spark_df)

Discussion
Rae
I tried using Cramkey dumps for my recent certification exam and I found them to be more accurate and up-to-date compared to other dumps I've seen. Passed the exam with wonderful score.
Rayyan Oct 10, 2026
I see your point. Thanks for sharing your thoughts. I might give it a try for my next certification exam.
Honey
I highly recommend it. They made a big difference for me and I'm sure they'll help you too. Just make sure to use them wisely and not solely rely on them. They should be used as a supplement to your regular studies.
Antoni Oct 16, 2026
Good point. Thanks for the advice. I'll definitely keep that in mind.
Alessia
Amazing Dumps. Found almost all questions in actual exam whih I prepared from these valuable dumps. Recommended!!!!
Belle Oct 28, 2026
That's impressive. I've been struggling with finding good study material for my certification. Maybe I should give Cramkey Dumps a try.
Billy
It was like deja vu! I was confident going into the exam because I had already seen those questions before.
Vincent Oct 1, 2026
Definitely. And the best part is, I passed! I feel like all that hard work and preparation paid off. Cramkey is the best resource for all students!!!
Page: 4 / 5

Databricks-Machine-Learning-Associate
PDF

$27.5  $109.99

Databricks-Machine-Learning-Associate Testing Engine

$32.5  $129.99

Databricks-Machine-Learning-Associate PDF + Testing Engine

$42.5  $169.99
