Weekend Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Machine-Learning-Associate Exam Questions and Answers by syeda

Page: 3 / 5

Databricks Databricks-Machine-Learning-Associate Exam Overview :

Exam Name: Databricks Certified Machine Learning Associate Exam
Exam Code: Databricks-Machine-Learning-Associate Dumps
Vendor: Databricks Certification: ML Data Scientist
Questions: 74 Q&A's Shared By: syeda
Question 12

A data scientist has a Spark DataFrame spark_df. They want to create a new Spark DataFrame that contains only the rows from spark_df where the value in column discount is less than or equal 0.

Which of the following code blocks will accomplish this task?

Options:

A.

spark_df.loc[:,spark_df["discount"] <= 0]

B.

spark_df[spark_df["discount"] <= 0]

C.

spark_df.filter (col("discount") <= 0)

D.

spark_df.loc(spark_df["discount"] <= 0, :]

Discussion
Question 13

A data scientist has created two linear regression models. The first model uses price as a label variable and the second model uses log(price) as a label variable. When evaluating the RMSE of each model bycomparing the label predictions to the actual price values, the data scientist notices that the RMSE for the second model is much larger than the RMSE of the first model.

Which of the following possible explanations for this difference is invalid?

Options:

A.

The second model is much more accurate than the first model

B.

The data scientist failed to exponentiate the predictions in the second model prior tocomputingthe RMSE

C.

The datascientist failed to take the logof the predictions in the first model prior to computingthe RMSE

D.

The first model is much more accurate than the second model

E.

The RMSE is an invalid evaluation metric for regression problems

Discussion
Question 14

A data scientist wants to use Spark ML to impute missing values in their PySpark DataFrame features_df. They want to replace missing values in all numeric columns in features_df with each respective numeric column’s median value.

They have developed the following code block to accomplish this task:
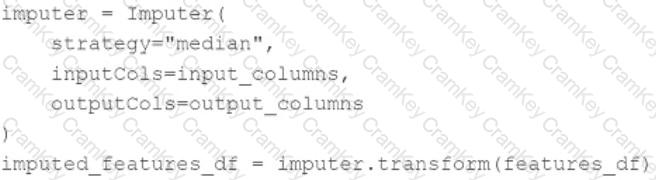
Questions 14

The code block is not accomplishing the task.

Which reasons describes why the code block is not accomplishing the imputation task?

Options:

A.

It does not impute both the training and test data sets.

B.

The inputCols and outputCols need to be exactly the same.

C.

The fit method needs to be called instead of transform.

D.

It does not fit the imputer on the data to create an ImputerModel.

Discussion
Freddy
I passed my exam with flying colors and I'm confident who will try it surely ace the exam.
Aleksander Oct 22, 2026
Thanks for the recommendation! I'll check it out.
Conor
I recently used these dumps for my exam and I must say, I was impressed with their authentic material.
Yunus Oct 16, 2026
Exactly…….The information in the dumps is so authentic and up-to-date. Plus, the questions are very similar to what you'll see on the actual exam. I felt confident going into the exam because I had studied using Cramkey Dumps.
Rae
I tried using Cramkey dumps for my recent certification exam and I found them to be more accurate and up-to-date compared to other dumps I've seen. Passed the exam with wonderful score.
Rayyan Oct 10, 2026
I see your point. Thanks for sharing your thoughts. I might give it a try for my next certification exam.
Fatima
Hey I passed my exam. The world needs to know about it. I have never seen real exam questions on any other exam preparation resource like I saw on Cramkey Dumps.
Niamh Oct 1, 2026
That's true. Cramkey Dumps are simply the best when it comes to preparing for the certification exam. They have all the key information you need and the questions are very similar to what you'll see on the actual exam.
Osian
Dumps are fantastic! I recently passed my certification exam using these dumps and I must say, they are 100% valid.
Azaan Oct 14, 2026
They are incredibly accurate and valid. I felt confident going into my exam because the dumps covered all the important topics and the questions were very similar to what I saw on the actual exam. The team of experts behind Cramkey Dumps make sure the information is relevant and up-to-date.
Question 15

A machine learning engineer is trying to scale a machine learning pipeline by distributing its feature engineering process.

Which of the following feature engineering tasks will be the least efficient to distribute?

Options:

A.

One-hot encoding categorical features

B.

Target encoding categorical features

C.

Imputing missing feature values with the mean

D.

Imputing missing feature values with the true median

E.

Creating binary indicator features for missing values

Discussion
Page: 3 / 5

Databricks-Machine-Learning-Associate
PDF

$33  $109.99

Databricks-Machine-Learning-Associate Testing Engine

$39  $129.99

Databricks-Machine-Learning-Associate PDF + Testing Engine

$51  $169.99
